Reinforcement Learning Course
How do AI teams use RL in production?
RL Part 13: An exploration of real-world RL case studies.
A collection of 14 posts
RL Part 13: An exploration of real-world RL case studies.
RL Part 12: From a single judged group to a full multi-step training loop with ART and RULER.
RL Part 11: From verifiable rewards to LLM-as-a-judge.
RL Part 10: Dropping two models from the four-model pipeline, and building rewards you can trust.
Part 9: From human preferences to a trained reward signal, and the four-model PPO pipeline.
RL Part 8: Trust regions, the clipped surrogate, and the workhorse of modern RL.
RL Part 7: Learning the policy directly, from REINFORCE to actor-critic.
RL Part 6: From linear features to neural networks, and the engineering choices that makes deep value-based RL possible.
RL Part 5: From tables to parameterized value functions.
RL Part 4: Learning value functions and policies without a model. Monte Carlo methods, TD(0), SARSA, Q-learning, and the bias-variance bridge between them.
RL Part 3: Bellman expectation and optimality equations, policy iteration, value iteration, and why dynamic programming needs a model.
RL Part 2: Markov decision processes, returns, policies, and value functions.
RL Part 1: Agents, environments, rewards, and why RL is different from supervised learning.
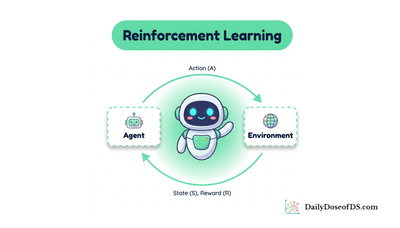
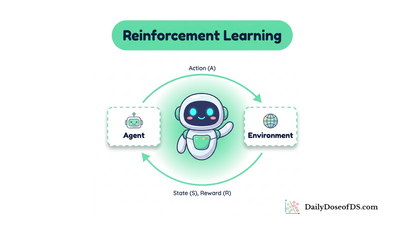
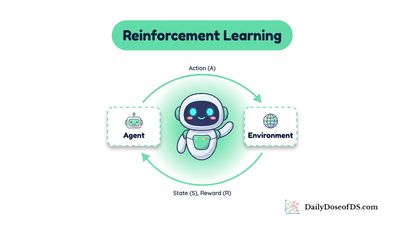
A series of technical deep dives on Reinforcement Learning that covers fundamentals and background, the classical techniques, MDPs, Bellman equations, deep RL methods, how RL is used to train modern language models, agentic RL, and much more.