AI Agents Course
First Steps Towards a Production-Ready Agent with LangChain
Part 1: Tools, structured output, runtime context, and tracing, in one small agent.
Part 1: Tools, structured output, runtime context, and tracing, in one small agent.
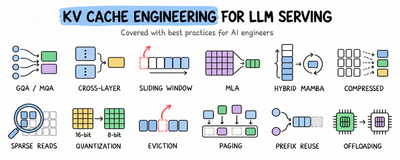
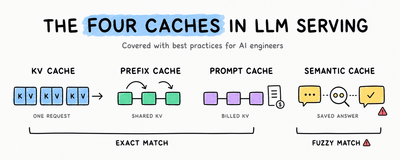
12 techniques to manage KV cache in production.
Part 15: Block-Attention, Cartridges, and what running preloading in production actually involves, with implementations
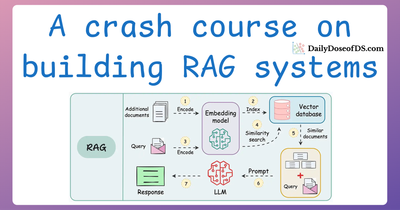
...explained with best practices in production.
Everything you need to understand, set up, and get real work out of Grok Bot.
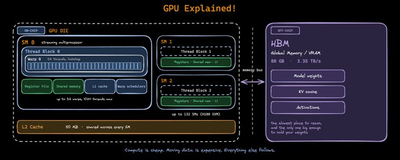
The intuition an LLM engineer needs, without the hardware manual. By the end, techniques like quantization, speculative decoding, and continuous batching should stop looking like a list of tricks to memorize.
Part 14: Shrinking a preloaded cache and the problems with those approaches, covered with implementations
Part 13: Reading the corpus once before any query arrives, and the two limitations that decide whether it works in production, with implementations