MLOps/LLMOps Course
Concepts of LLM Serving
LLMOps Part 14: An overview of the fundamentals of LLM serving, including API-based access, inference with vLLM, and practical decisions.
LLMOps Part 14: An overview of the fundamentals of LLM serving, including API-based access, inference with vLLM, and practical decisions.
LLMOps Part 13: Exploring the mechanics of LLM inference, from prefill and decode phases to KV caching, batching, and optimization techniques that improve latency and throughput.
...explained visually.
LLMOps Part 12: Understanding LLM fine-tuning, parameter-efficient methods like LoRA and QLoRA, and alignment techniques such as RLHF, DPO, and GRPO.
...explained visually!
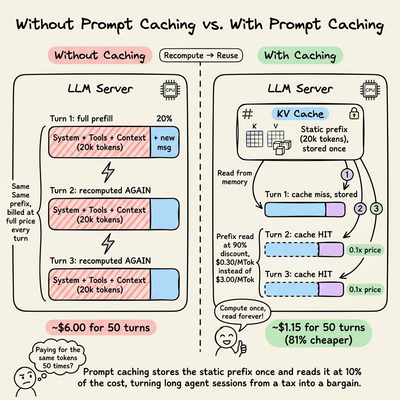
A case study on how Claude achieves 92% cache hit-rate.
LLMOps Part 11: Understanding evaluation of conversational LLM systems, tool evaluations, tracing with Langfuse, and automated red teaming.
LLMOps Part 10: Understanding model benchmarks, LLM application evaluation, and tooling.